The idea: grow the tree where it looks good
A game program has to pick a move. Minimax looks at every position down to the end, or down to a fixed depth with an evaluation function. That is too much for a game like Go. Monte Carlo Tree Search (MCTS) does something cheaper. It plays many quick random games (playouts) and keeps a tree of the positions it has visited. Each node stores two numbers: n, how many playouts went through it, and w, how many of them were won by the player who made the move into it. The tree grows by one node per iteration, mostly under the moves that win often.
The page uses a tiny game so the whole tree fits: Nim with 5 stones. Players A and B take 1 or 2 stones in turn, and whoever takes the last stone wins. A moves first. The full game has 20 positions; each one has a fixed spot on the canvas, so you can watch the search tree fill it in.
One iteration in four phases
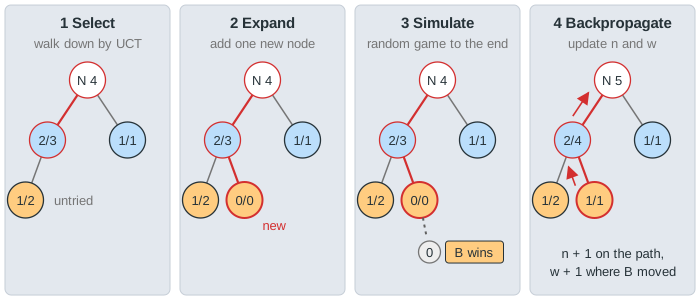
- Select. Start at the root. While every move of the node has been tried, go to the child with the highest UCT score (next section).
- Expand. The node has an untried move: add one child for it, with 0/0.
- Simulate. From the new node, both players make random moves until the game ends. This playout is not stored; on the canvas it is the dashed path through grey positions.
- Backpropagate. Every node on the path gets n + 1, and w + 1 if the player who moved into it won the playout.
If selection reaches the end of the game, there is nothing to expand or simulate: the result is simply who took the last stone. (Demo 1: one iteration in 4 phases runs five quick iterations and then a slow one.)
UCT: exploit plus explore
Selection uses UCT (Upper Confidence bounds applied to Trees, Kocsis and Szepesvári, 2006). For a child with n visits and w wins, under a parent with N visits:
| term | what it rewards | how it changes |
|---|---|---|
w/n (exploit) | moves that won often so far | settles towards the true win rate |
c·√(ln N / n) (explore) | moves tried little compared with their parent | shrinks as n grows, grows slowly as N grows |
Because w counts wins for the player who moved into the child, the player to move at each node picks what is best for them: A maximises A's wins at A's nodes and B maximises B's wins at B's nodes. That is the minimax idea, done with averages.
The exploration constant c
The textbook value is c = √2 ≈ 1.41 for results in 0..1. A small c trusts the first results. A large c keeps trying every move. With the same random numbers and 20 iterations:
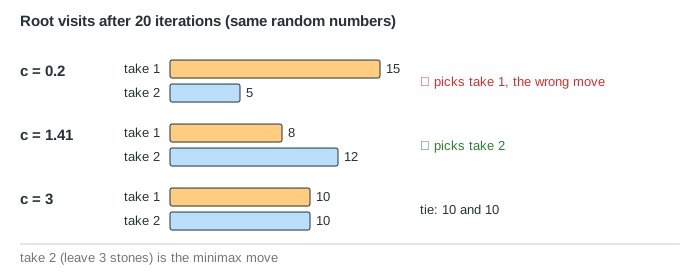
With c = 0.2, take 1 wins its first few random playouts, and the search keeps going there; take 2, the right move, gets only 5 of 20 visits (Demo 3). With c = 3 the visits split 10 and 10 and the tree is wider (Demo 4). Run longer and both recover, but a real game gives the search a fixed time budget.
Choosing the move: most visits
After the budget is spent, play the root child with the most visits (the "robust child"). A move tried twice with 2/2 has a perfect win rate but tells you little; a move with 17/19 has been tested. Since UCT sends more visits to better moves, visits are a steadier signal than win rate. Ties are rare; the page breaks them by win rate (Demo 5).
MCTS vs minimax
| Minimax / alpha-beta | MCTS | |
|---|---|---|
| what it searches | every move to a fixed depth (alpha-beta skips some) | a tree that grows unevenly, toward promising moves |
| value of a position | evaluation function at the depth limit | average result of random playouts |
| stopping | when the depth is done | any time: more iterations, better estimate |
| branching factor | hurts a lot (bd) | copes: rarely visited moves stay shallow |
| answer | exact for the searched depth | converges to the minimax move as iterations grow |
In this Nim game, positions with a multiple of 3 stones are lost for the player to move, so minimax says take 2 (leave 3). Demo 6 runs 40 iterations: take 2 gets 28 of 40 visits, and the page labels each root move with its minimax result.
Where MCTS is used
MCTS made computer Go strong around 2006–2012 and is the search inside AlphaGo and AlphaZero. AlphaZero keeps the four phases but replaces the random playout with a neural network that predicts the value of a position, and adds the network's move probabilities to the selection score (PUCT). It is also used in general game playing, planning and some puzzle solvers, anywhere a simulator exists but a good evaluation function does not. Its explore/exploit trade-off is the same one an agent faces in Q-learning with ε-greedy.
Monte Carlo Estimation of π shows the same idea in its simplest form: the share of random trials that succeed estimates a probability, with error shrinking like 1/√n.
What the page leaves out
Real programs run thousands to millions of iterations per move, reuse the subtree of the move actually played, and run iterations in parallel (with "virtual loss" so threads spread out). Playouts are often guided by cheap heuristics instead of being uniformly random, and draws count as half a win. Variants such as RAVE/AMAF share statistics between moves, and expansion may add all children at once. The page also fixes the order of untried moves (take 1 first) and uses one random seed so every run and undo is the same.