The idea: merge sort as passes, not recursion
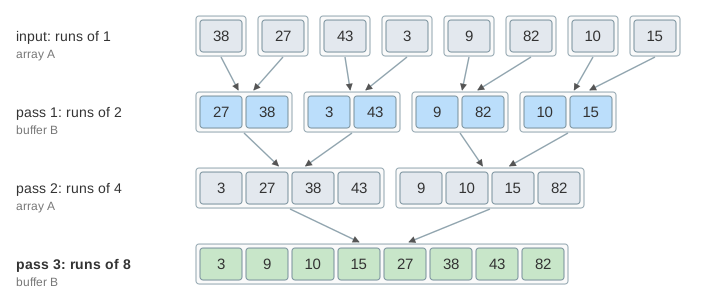
Ordinary merge sort splits the array in half, sorts each half by calling itself, then merges. All the real work happens in the merges, and the splitting only decides which pieces get merged. Bottom-up merge sort skips the splitting. It starts with n sorted runs of length 1 (one item is always sorted), and makes passes over the array. Each pass merges neighbouring runs in pairs, so the runs double: 1, 2, 4, 8, until one run covers everything.
One pass, in code
for (w = 1; w < n; w *= 2)                 // one pass per run width
    for (lo = 0; lo < n; lo += 2*w)        // pair up runs from the left
        mid = min(lo + w, n)
        hi  = min(lo + 2*w, n)
        merge(src[lo..mid), src[mid..hi)  into  dst[lo..hi))
    swap(src, dst)                          // the next pass reads what this one wrote
Two loops and no call stack. The canvas draws one row per pass so you can see every width at once: row p holds sorted runs of 2p (Demo: sort 8 numbers in 3 passes).
The merge step
Both runs are already sorted, so the smallest item not yet taken is one of the two heads. Compare the heads (one comparison), move the smaller one to the next free slot, and repeat. When one run is used up, the rest of the other run is copied with no comparisons: it is sorted and no smaller than anything taken. Merging two runs with k items in all costs at most k − 1 comparisons. On the canvas the left run is blue, the right run orange, and each item keeps its run's colour in the row below (Demo: one pass merges every pair of runs of 1).
When n is not a power of 2
With n = 11 the pairs do not come out even. In pass 1 the last item has no partner, and in pass 3 the run [8, 11) has none either. Such a lone run is copied down as it is (purple on the canvas). Later it gets merged with a run much longer than itself: the last pass merges 8 items with 3. The number of passes is still ⌈log2 n⌉ = 4 (Demo: n = 11, a lone run at the end of a pass).
Cost
Every pass moves each item exactly once, and there are ⌈log2 n⌉ passes, so the sort always does n ⌈log2 n⌉ moves and O(n log n) work, whatever the input. Comparisons depend on the input, but never exceed the sum of (merge length − 1).
| Demo | n | Comparisons per pass | Total | Most possible |
|---|---|---|---|---|
| Sort 8 numbers | 8 | 4 + 6 + 7 | 17 | 17 |
| Lone run, n = 11 | 11 | 5 + 7 + 7 + 9 | 28 | 30 |
| Already sorted | 16 | 8 + 8 + 8 + 8 | 32 | 49 |
| 16 numbers | 16 | 8 + 12 + 14 + 14 | 48 | 49 |
Sorted input is the cheapest case: every left run is used up after w comparisons, so each pass costs n/2. But it still takes all 4 passes and all 64 moves. Plain bottom-up merge sort does not notice that the input is sorted (Demo: already sorted input still takes every pass). A common fix is to skip a merge when the last item of the left run is ≤ the first of the right run.
Two arrays, ping-pong
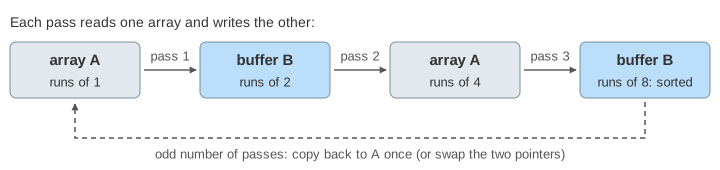
A merge cannot write over the runs it is still reading, so the sort needs a second array of size n: the buffer. Instead of copying back after every merge, each pass reads one array and writes the other, and the next pass swaps their roles. That is why the canvas rows are labelled A, B, A, B. After an odd number of passes the result is in B, and a real sort copies it back once (or just swaps the two pointers).
Equal keys: the sort is stable
When the two heads are equal, the merge takes the left one. The left run holds items that came earlier in the input, so equal keys keep their input order. The demo tags equal values with letters: 1a, 1b and 1c come out in that order (Demo: equal keys keep their order). Taking the right head on a tie would still sort the numbers, but would lose stability.
Top-down vs bottom-up
| Top-down (recursive) | Bottom-up (this page) | |
|---|---|---|
| Control | Recursion, call stack depth log2 n | Two loops, no stack |
| Which runs merge | Halves of each subarray, so sizes stay balanced | Fixed widths 1, 2, 4, ...; the last merge of a pass may be uneven |
| Order of work | Depth first: finishes the left half before touching the right | Breadth first: one sweep over the whole array per pass |
| Time, extra space | O(n log n), O(n) | O(n log n), O(n) |
| Good for | Arrays in memory, cache-friendly small subproblems | Linked lists, files and tapes read in sequence, runs found in the data |
For a power of 2 both versions do exactly the same merges, only in a different order.
Where it is used
- TimSort (Python, Java's object sort) uses the same pass idea, but its starting runs are the ascending stretches already in the data, extended by insertion sort, not single items.
- External sort: sort chunks that fit in memory into runs on disk, then merge runs in passes. Each pass reads and writes every item once, in sequence, which is what disks are good at.
- Linked lists: bottom-up merge sort needs no random access and no extra array, so it is the usual way to sort a list in O(n log n).
See also: the recursive version against quicksort on Quick Sort vs Merge Sort; runs found in the data on TimSort; merging many runs at once with a heap on K-way Merge; other sorts step by step on Comparison Sorting and Sorting Race; and the recurrence T(n) = 2T(n/2) + n on Master Theorem.
What the page leaves out
Starting from runs longer than 1 (insertion sort on small blocks, as real libraries do); the "already in order, skip the merge" check; galloping merges; in-place merging without a buffer; merging more than two runs per pass (multiway passes in external sort); the final copy back from B to A.
See where this page fits on the Sorting mind map.