The idea: a bigger server, or more servers
When a service gets more traffic than one server can handle, there are two ways to grow. Scale up (vertical scaling) moves it to a bigger machine: more CPU cores, more memory. Scale out (horizontal scaling) adds more machines of the same size and puts a load balancer in front of them. This page runs both under the same load, side by side, and keeps score: cost per month, downtime and failed requests, and latency.
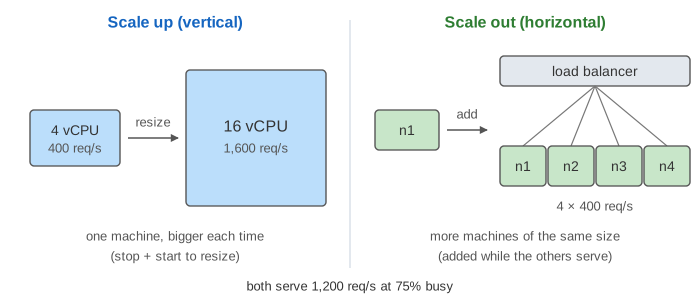
The model is small and real. Load ×1 is 300 requests per second, one vCPU serves 100 requests per second, and both sides are sized to stay at most 75% busy (a common autoscaling target). Cloud prices are close to linear per vCPU, so the page uses $35 per vCPU-month, $20 for the load balancer and $50 for a Redis session store. Latency follows the usual rule of thumb: service time ÷ (1 − utilization), with 10 ms of work per request and 1 ms for each extra network hop.
Scale up: one bigger machine
The code does not change at all. The database, the cache and the user sessions all stay in one process, and requests never cross the network inside the system. That is why scaling up is the first thing most teams do. Its costs show up elsewhere:
- Resizing means downtime. A cloud VM must be stopped to change its instance type, then started again (here 120 s). Every request in that window fails. Demo: load ×4 (ramp up) resizes twice: 240 s down and 108,000 failed requests.
- Sizes come in doubling steps. 900 req/s needs 12 vCPU, but the next size is 16, so you pay for capacity you do not use (and get lower latency from it: 23 ms instead of 41 ms).
- There is a largest machine. Here it is 64 vCPU. In Demo: the hardware ceiling the load reaches 9,600 req/s and the biggest server can serve only 6,400: a third of the requests are refused.
Scale out: more machines
New nodes boot while the old ones keep serving, and the load balancer adds each one after its health check passes. Nothing goes down, the steps are one node (400 req/s) at a time, and there is no ceiling in sight. When the load falls, nodes are drained (no new requests, the ones in flight finish) and then terminated. Demo: load drops ×4 → ×1: scale out goes from $580 to $160 a month with no downtime; scale up must either keep paying for 16 vCPU or take another 120 s outage to shrink.
The price is extra parts and an extra hop: the load balancer adds about 1 ms to every request and costs money of its own. At ×4 the two sides cost almost the same ($560 vs $580).
Failures: single point of failure vs N − 1
One big server is a single point of failure. When it crashes, the whole site is down until it is rebooted or replaced. Four nodes lose a quarter of their capacity when one crashes. The load balancer notices through its health checks (every 5 s, two failures in a row), so only the dead node's share fails for 10 s, and a replacement joins 90 s later.
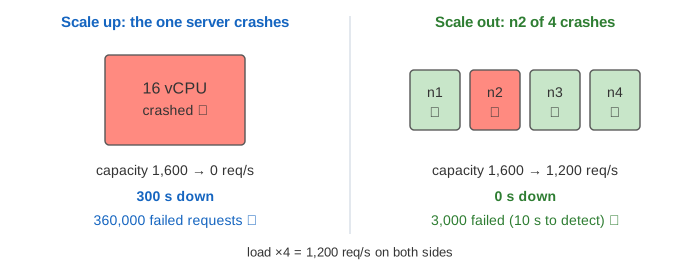
Look at what is left, though: three nodes for 1,200 req/s is 100% busy, so requests queue and slow down until the replacement arrives. Real systems keep N + 1 (or more) nodes so that losing one still leaves headroom. Demo: one server fails shows both sides.
State: the sessions problem
Scaling out only works if any node can serve any request. A session kept in one node's memory breaks that. In Demo: sessions in server memory, Alice logs in on n1; round robin sends her next request to n2, which has never seen her session, so she gets 401 and is logged out. The single big server has no such problem.
There are two fixes. Sticky sessions make the balancer send a user back to the same node (see Load Balancer), but the session is lost when that node dies. A shared session store such as Redis keeps the nodes stateless: every node reads the session from the store. Demo: sessions in Redis works on both sides, for $50 more a month and one more hop per request. The same rule applies to uploaded files, caches and in-process locks: move state out of the nodes before scaling out. For the database itself, see partitioning vs sharding.
When to pick which
| Scale up | Scale out | |
|---|---|---|
| Code changes | none | stateless nodes, shared store, a load balancer |
| Growing | stop + start: minutes of downtime | add nodes while serving |
| Steps | doubling instance sizes | one node at a time |
| Limit | the largest machine | the shared parts (database, store, balancer) |
| One machine fails | everything is down | 1/N of the capacity is gone |
| Latency | lowest: no network hops inside | +1 hop per shared part |
| Load falls | keep paying, or resize down (downtime) | drain and remove nodes |
| Good for | databases, small services, quick relief | stateless web and API tiers, spiky traffic |
Most real systems do both: they scale the stateless tier out and the database up (until it, too, has to be sharded). The latency numbers come from queueing; see latency vs throughput for why a server at 100% busy is slow even before it refuses anything.
What the page leaves out
Real instance families go far beyond 64 vCPU (some have hundreds of cores and terabytes of memory), and big machines rarely scale linearly: cores contend for locks, memory bandwidth and caches (Amdahl's law, the Universal Scalability Law). Some clouds can resize memory or CPU live. Autoscalers react to load after the fact, so a sudden spike hits before new nodes are up; the page sizes both sides ahead of time. It also leaves out the database tier, replication, connection limits, multiple availability zones and the operations cost of running many machines.