The idea: a comparison sort is a decision tree
Merge sort, heap sort, quicksort and insertion sort all learn about the keys in one way only: they ask "is x < y?" and get yes or no. Fix the number of keys n. Then every run of the algorithm is a path in a binary tree, the decision tree. Each inner node is one compare, its two edges are the two answers, and each leaf is the order the algorithm finally outputs.
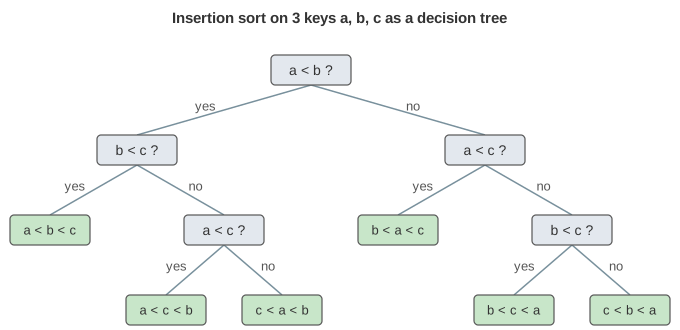
The canvas draws the tree of insertion sort on 3 keys a, b, c. Pick an input and press Sort by Comparisons: each question lights up, its answer takes one edge, and the leaves under the other edge turn grey. (Demo: sorted input needs only 2 compares, Demo: a worst-case input needs 3 compares)
n! leaves need height log₂ n!
A correct sort must give a different output for each of the n! orders of the input. Two orders that end in the same leaf would get the same rearrangement, and one of them would come out wrong. So the tree has at least n! leaves.
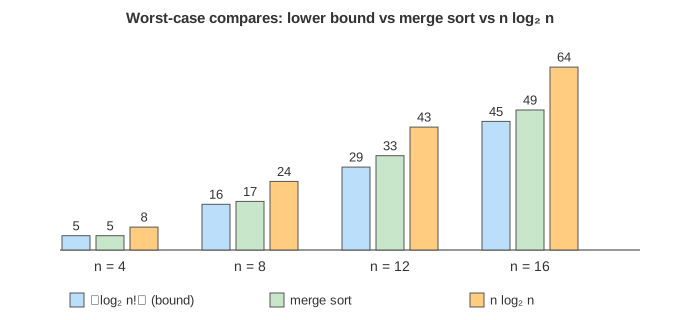
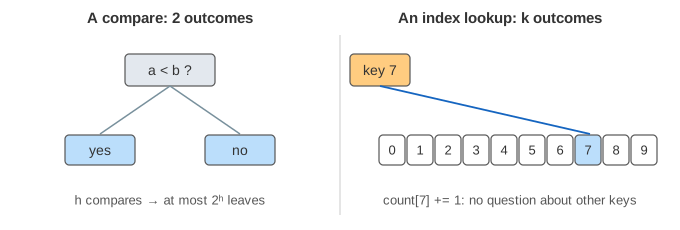
A binary tree of height h has at most 2h leaves. So 2h ≥ n!, which means h ≥ log₂ n!. The height is the number of compares on the longest path, that is, the worst case. For 3 keys: 6 leaves, so at least ⌈log₂ 6⌉ = 3 compares.
| n | n! orders | ⌈log₂ n!⌉ (fewest worst-case compares) | merge sort, worst case |
|---|---|---|---|
| 3 | 6 | 3 | 3 |
| 4 | 24 | 5 | 5 |
| 5 | 120 | 7 | 8 |
| 10 | 3,628,800 | 22 | 25 |
| 20 | 2.4 × 10¹⁸ | 62 | 69 |
(Demo: n! leaves grow like n log n)
The adversary argument
The same bound has a game form. An adversary does not pick the input in advance. When the algorithm asks a question, the adversary looks at the orders that are still possible and answers so that the larger group survives. Each answer can then at best cut the possible orders in half, so it takes at least log₂ n! answers to get down to one. At the end the adversary names an input that fits every answer it gave, so the run was real. On the canvas: 6 → 3 → 2 → 1, three compares. (Demo: the adversary forces 3 compares)
log₂ n! is about n log₂ n
log₂ n! = log₂ 1 + log₂ 2 + … + log₂ n. Half of those terms are at least log₂(n/2), so the sum is at least (n/2) log₂(n/2). Stirling's formula gives the sharp form: log₂ n! ≈ n log₂ n − 1.44 n. So every comparison sort needs Ω(n log n) compares in the worst case (and on average too). Merge sort and heap sort reach O(n log n), so they are optimal up to a constant factor.
Why counting sort and radix sort can beat it
The bound is about algorithms whose only access to the keys is a compare. Counting sort does something else: it uses a key as an array index. Key 7 goes straight to count[7], with no question about the other keys. One step can then have k outcomes instead of 2, so the decision-tree argument says nothing. For n integers in the range 0..k−1 it runs in O(n + k). Radix sort repeats a counting pass once per digit, O(d·(n + b)) for d digits in base b. The price is an assumption about the keys: small integers or fixed-length digit strings. (Demo: counting sort uses 0 compares)
See also Comparison Sorting for the sorts this bound applies to, Quick Sort vs Merge Sort for two O(n log n) sorts side by side, and Sorting Networks, where the compares are fixed in advance.
What the page leaves out
The page draws only n = 3 and only insertion sort's tree. It leaves out the average-case bound (the average leaf depth is also at least log₂ n!), Ford–Johnson merge insertion, which needs fewer compares than merge sort and meets the bound for small n, the cases where the bound is not reached (n = 12 needs 30, not 29), lower bounds for related problems such as element distinctness in algebraic decision trees, and integer sorts faster than O(n log n) on the word RAM.
See where this page fits on the Sorting mind map.