The idea: many variables, few registers
A program can use as many variables as it likes, but the CPU has only a few registers (16 general-purpose ones on x86-64, 31 on ARM64). Values in registers are fast; values in memory need a load or a store. Register allocation is the compiler pass that decides which variable lives in which register, and which ones have to live in memory instead. The classic method, due to Chaitin, turns the problem into graph coloring: variables are nodes, "can't share a register" is an edge, and the k registers are k colors.
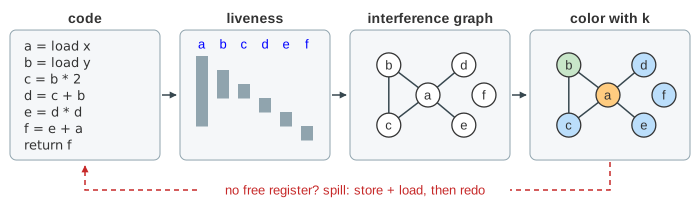
The page runs the whole pass on one small basic block of six variables, a to f:
1  a = load x
2  b = load y
3  c = b * 2
4  d = c + b
5  e = d * d
6  f = e + a
7  return f
Liveness: a backward scan
A variable is live at a point if the value it holds there may still be read later. A dead value doesn't need a register any more. Liveness flows backwards, so the scan starts at the last line, where nothing is live, and walks up. For each instruction:
live-before = (live-after − defined here) ∪ used here
The page draws live-after of each line as bars, one column per variable. A column of filled rows is
that variable's live range. (Demo: liveness, a backward scan)
| line | instruction | live after | live before |
|---|---|---|---|
| 7 | return f | {} | {f} |
| 6 | f = e + a | {f} | {a, e} |
| 5 | e = d * d | {a, e} | {a, d} |
| 4 | d = c + b | {a, d} | {a, b, c} |
| 3 | c = b * 2 | {a, b, c} | {a, b} |
| 2 | b = load y | {a, b} | {a} |
| 1 | a = load x | {a} | {} |
a is loaded first and read only at line 6, so its range is the longest: it is live across five lines
while doing nothing.
The interference graph
Two variables interfere when they hold values at the same time, so they need different registers.
The rule a compiler uses: when an instruction defines d, add an edge from d to every other
variable live after it. On the bars it is simply "two bars share a row". (Demo: interference graph from the live
ranges)
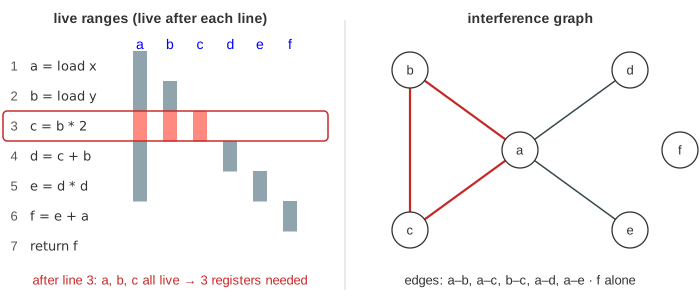
Here the edges are a–b, a–c, b–c, a–d and a–e. a has degree 4, f has none.
Simplify and select
Coloring a graph with k colors is NP-hard in general (see Graph Coloring), so allocators use Chaitin's simple trick. If a node has fewer than k neighbours, it can always be colored later: even if every neighbour takes a different color, one is left over. So:
- Simplify: remove such a node and its edges, push it on a stack. Removing it lowers its neighbours' degrees, which often makes more nodes safe.
- Select: when the graph is empty, pop the nodes in reverse order. Each one goes back into the graph and gets the lowest register that none of its already colored neighbours uses.
With k = 3 every node becomes safe in turn and the block gets three registers with no memory traffic. (Demo: k = 3 registers, everything fits) With k = 4 simplify never gets stuck, and still only three registers are used: one stays free. (Demo: k = 4, one register to spare)
Spilling
With k = 2, after removing f, d and e, the triangle a, b, c is left
and every node has 2 neighbours: simplify is stuck. The allocator then picks a spill candidate, the
node that is cheapest to keep in memory for each edge it removes:
| variable | spill cost (defs + uses) | degree | cost ÷ degree |
|---|---|---|---|
| a | 2 | 4 | 0.50 (lowest) |
| b | 3 | 2 | 1.50 |
| c | 2 | 2 | 1.00 |
Real compilers weight each use by how deep in loops it is (often 10depth), so a variable used inside a
hot loop is almost never spilled. Following Briggs, the candidate is pushed anyway, because it might still find a
free register in select. Here it doesn't: b and c take r1 and r2, so a is an
actual spill. It gets a stack slot [sp+0], and the code is rewritten:
a1 = load x
store a1 → [sp+0]      ← right after the definition
b = load y
...
a2 = load [sp+0]       ← right before the use
f = e + a2
The long live range of a becomes two tiny ones, a1 and a2. Liveness and the
graph are rebuilt; now at most 2 variables are live at once, and 2 registers are enough. The price is one store and
one load. (Demo: k = 2, spill a to the stack)
How many registers does a block need?
In straight-line code the live ranges are intervals, and an interval graph can always be colored with as many colors as the most intervals that overlap. So a basic block needs exactly MaxLive registers, the largest live set (3 here, after line 3). Loops and branches break this: liveness must be iterated over the control-flow graph until nothing changes, the graph can have long cycles, and simplify can get stuck even when k colors would be enough.
Beyond the basic algorithm
| technique | what it adds |
|---|---|
| coalescing | a copy x = y whose two ends don't interfere gets one register, and the copy disappears |
| precolored nodes | arguments, return values and call-clobbered registers are fixed by the calling convention (see MIPS procedure calls) |
| live-range splitting | spill only part of a range instead of every use |
| linear scan | walk the live intervals in order, no graph: much faster, used by JIT compilers (HotSpot C1, V8) |
| SSA-based allocation | in SSA form the interference graph is chordal, so it colors optimally in polynomial time |
Register allocation runs late in the compiler back end, after instruction selection; see Compiler vs Interpreter for where compiling fits.
What the page leaves out
The page uses one basic block, so there are no loops, branches or iterative dataflow. It leaves out copy instructions and coalescing, precolored registers and the calling convention (caller- and callee-saved registers), loop-weighted spill costs, spilling several variables in one round, reusing stack slots, rematerialization (recomputing a constant instead of loading it), and instructions that can read an operand straight from memory as x86 can.