The idea: one copy of the file in RAM
When a program reads a file on Linux, the bytes do not go straight from the disk to the program.
The kernel first reads them into the page cache: a pool of 4 KB pages in kernel RAM,
indexed by (file, page number). Every reader of the file is then served from that one copy.
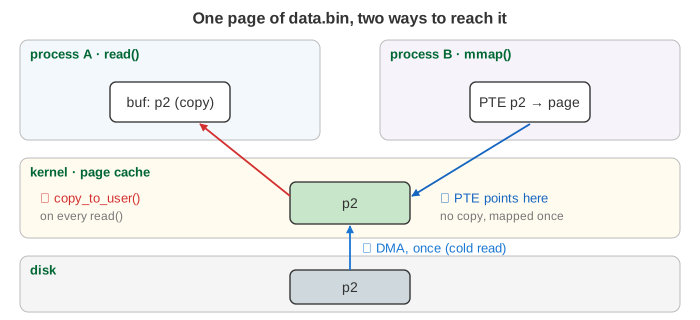
There are two ways to get at it. read() asks the kernel to copy the bytes
into the program's own buffer. mmap() asks the kernel to map the page cache
page into the program's address space, so the program reads it in place.
The canvas runs both on one small file, data.bin, of 8 pages (32 KB). Process A on the
left uses pread(fd, buf, 4096, n × 4096). Process B on the right maps the whole file once
with mmap() and then loads and stores through the pointer. In the middle is the kernel's
page cache for this file (one slot per page), and at the bottom the disk. Each side counts its
system calls, its CPU copies, its page faults and its
disk reads and writes. Blue lines are B's page table entries (PTEs), each pointing at
the page it maps.
The page cache: cold and warm
The first read of a page is cold: the page is only on disk. The kernel finds no page in the cache (a miss), allocates one, and asks the disk controller to fill it with DMA. The process sleeps until the I/O is done. The next read of the same page is warm: the page is in RAM (a hit) and no disk is involved (Demo: read() cold, then warm: 2 reads, 1 disk read).
A miss rarely reads just one page. The kernel bets that a program that reads page n will soon read
n + 1, n + 2, … and reads a whole window in one I/O: read-ahead. On the canvas the window
is 4 pages; the real default is read_ahead_kb = 128 KB, 32 pages, and the window grows
while the reads stay sequential. Reading pages p0 to p4 one after another costs only 2 disk reads,
p0–p3 and p4–p7 (Demo: sequential read() and read-ahead). The cache is shared by all
processes: after A's read of p0, B's first touch of p0 and p1 needs no disk at all
(Demo: one page cache for both).
Free RAM does not stay free on Linux: it fills up with page cache. That is the buff/cache
column of free. Clean pages are dropped when memory is needed (see
Page Replacement), so a big cache costs nothing.
read(): a system call and a copy, every time
Each read() is a system call: the CPU switches from user mode into the
kernel, the kernel finds the page in the cache (filemap_read()), and then
copy_to_user() copies the bytes into the caller's buffer. The copy is CPU work, and it
happens on a hit too. After it, the data sits in RAM twice: in the page cache and in
buf. A program that reads 8 pages with 4 KB reads makes 8 system calls and 8 copies.
Bigger reads mean fewer calls, but the same number of bytes copied.
In exchange, the buffer is the program's own: it can change it freely, and later writes to the file
by others do not change it. And read() works on pipes and sockets too, where there is no
page to map.
mmap(): one call, a fault per page, then plain loads
mmap(NULL, 32768, PROT_READ|PROT_WRITE, MAP_SHARED, fd, 0) is one system call. It reads
nothing. The kernel only records a VMA (virtual memory area): the range of addresses
that now stands for the file. B's PTEs for that range are still empty.
The first load from a page hits an empty PTE, so the MMU raises a page fault. The
kernel's fault handler (filemap_fault()) finds the page in the page cache, reading it from
disk first on a miss, and writes B's PTE to point at that very page. No byte is
copied. The CPU retries the load and it succeeds. From then on every load from that page is a plain
memory read through the MMU, with no kernel at all
(Demo: mmap() cold, then warm: 1 system call, 1 fault, 0 copies).
How the MMU walks the page table is on Linux Virtual Memory.
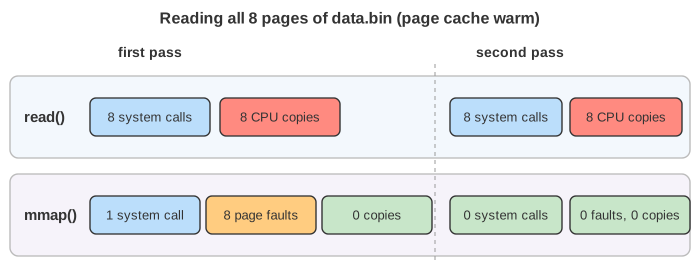
A page fault is not free: it is an exception into the kernel, about as costly as a system call, and
the kernel must later tear the mapping down (munmap(), TLB shootdowns on other CPUs). So
mmap() wins when a program touches the same pages many times or jumps around in a large file, and it
is not a big win for one sequential pass. Real kernels soften the per-page cost with
fault-around: one fault also maps the neighbouring pages that are already cached.
On a miss the fault handler reads around the page rather than ahead of it: on the
canvas a fault on p2 reads p0–p3.
Writes with MAP_SHARED: dirty pages, msync() and writeback
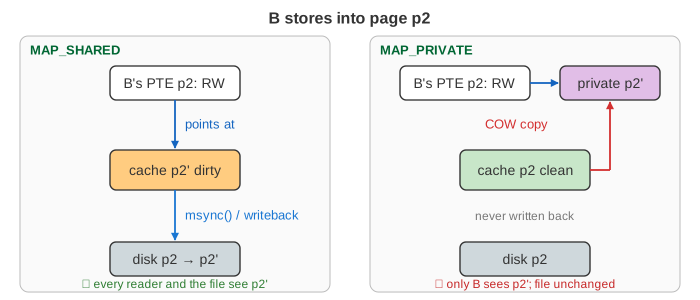
With MAP_SHARED, B's stores go into the page cache page itself. The first store to a
clean page faults even if the page is mapped: the kernel maps shared file pages read-only so that it
notices the first write. The handler (page_mkwrite) marks the page dirty
and makes the PTE writable. Later stores to that page are plain stores.
Because there is only one copy, a read() by any process sees B's change at once, before
it reaches the disk (Demo: MAP_SHARED write, then msync(): A's buffer gets
p2'). The disk gets it in one of two ways. msync(p, len, MS_SYNC) writes the
mapping's dirty pages now and waits. Or, about 30 s later
(dirty_expire_centisecs = 3000), a kernel flusher thread writes them back
on its own (Demo: dirty pages, kernel writeback: two pages, one write). After the write the
kernel write-protects the PTEs again, so the next store marks the page dirty again. A crash before the
write loses the stores; how a file system makes writes durable is on
How a File System Survives a Crash.
Writes with MAP_PRIVATE: copy on write
With MAP_PRIVATE, B gets the file's pages read-only too, shared with the page cache. The
first store to a page faults, and the kernel now makes a private copy: it allocates an
anonymous page, copies the page cache page into it (a CPU copy), and points B's PTE at the copy,
writable. The store goes into the copy. The page cache page stays clean, the file never changes, and
other processes keep seeing the original (Demo: MAP_PRIVATE write, copy on write: A still
reads p2 while B has p2'). This is how the loader maps a program's
.data section, and the same trick as fork()'s copy on
write.
Side by side
| read() | mmap() | |
|---|---|---|
| System calls | one per read | one mmap() (and munmap()) |
| Copies | page cache → buffer, every read | none (MAP_PRIVATE: one per written page) |
| Page faults | none | one per page on first touch |
| Cold page | disk read with read-ahead | disk read with read-around |
| Sees other writers | at the next read() | at once (MAP_SHARED) |
| Errors | a return value (-1, errno) | a signal (SIGBUS on a truncated file, an I/O error) |
| Works on | files, pipes, sockets | files and devices that support it |
| Good for | streaming once through a file | random access, reading many times, sharing |
Databases split on it. LMDB and older MongoDB storage map the whole file; PostgreSQL and InnoDB read
pages into their own buffer pool and control writeback themselves. Kafka avoids both copies on the send
path with sendfile(), see Kafka Zero Copy. Blocking on a
cold page, in read() or in a fault, is the problem async I/O tries to solve, see
Blocking vs Async I/O.
What the page leaves out
- Eviction: the whole file fits in the cache here; real caches drop clean pages under memory pressure (LRU lists,
kswapd). - The real read-ahead state machine: the 32-page default, async read-ahead (the
PG_readaheadmarker), window growth,posix_fadvise()andmadvise()hints. - Fault-around (
fault_around_bytes= 64 KB), which maps cached neighbours in one fault. write()into the page cache,fsync(),O_DIRECT(which skips the page cache) and huge pages.- The TLB, page table levels and the cost of
munmap()(TLB shootdowns). - Reads that cross page boundaries, file sizes that are not a multiple of 4 KB, and
SIGBUSpast the end of the file.