The idea: a write is not seen just because it happened
Two threads share an object. Thread T1 writes data = 42; and then ready = true;. Thread T2 waits with while (!ready) { } and then reads data. It looks safe, but with plain fields Java does not promise that T2 ever sees ready change, or that it sees data change first. The JIT compiler keeps values in registers and reorders code, and each CPU core has a store buffer and caches. The Java Memory Model (JMM, chapter 17.4 of the Java Language Specification) says exactly when a read must see a write: when the write happens-before the read.
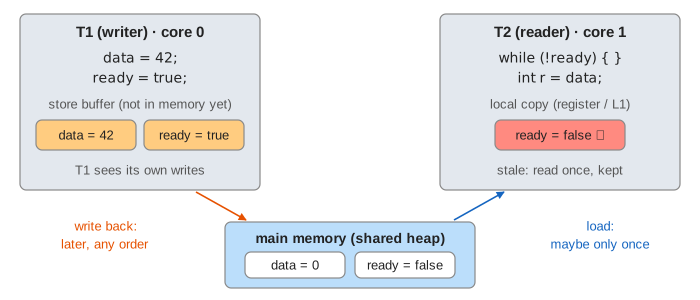
The page uses that picture. T1's writes go into its store buffer and reach main memory only when they are written back. T2 keeps a local copy (a register or its L1 cache) of each field it has read. Press Step T1, Step T2 and Write Back in any order and watch which values each thread can see.
Bug 1: the stale value (the loop never ends)
ready is a plain field, and nothing in the loop writes it. So the JIT may read it once and keep it in a register for the whole loop: if (!ready) while (true) { }. This is called hoisting, and HotSpot's C2 compiler really does it. If T2 reads ready == false before T1 sets it, T2 spins forever, even after main memory has ready = true. (Demo 2: plain, reader spins forever: T2 keeps spinning on its red, stale copy.)
Bug 2: reordering (ready is true, data is 0)
T1's two writes are to different fields and do not depend on each other, so the compiler and the CPU may make them visible in either order. On x86 the store buffer keeps stores in order, but the JIT may still swap them; on ARM and POWER the hardware itself may. If ready = true reaches memory first, T2 leaves the loop and reads data = 0. (Demo 3: plain, reordered writes, r = 0.) Demo 1: plain fields, lucky order prints 42, but only because the writes happened to arrive in program order: the code is still broken.
Happens-before
Both bugs are data races: two threads access one field, at least one writes, and no happens-before orders them. A racy program may see any of the values the race allows. Happens-before is built from a few rules, and it is transitive: if A happens-before B and B happens-before C, then A happens-before C.
| Rule | A happens-before B when |
|---|---|
| Program order | A comes before B in the same thread |
| Volatile | A writes a volatile field and B is a later read of that field that sees the value |
| Monitor lock | A unlocks a monitor and B is a later lock of the same monitor |
| Thread start / join | A is t.start() and B is in t; or A is in t and B follows t.join() |
| Final fields | the constructor's writes to final fields, for any thread that gets the object after the constructor ends |
If a write happens-before a read of the same field, the read must see that write (or a later one). That is the only promise. A sleep, a print or "it ran later" is not a happens-before edge.
The fix: volatile
Declare volatile boolean ready;. A volatile write is a release: every earlier write of the thread must become visible first. A volatile read is an acquire: it always reads the current value from memory, and later reads cannot be moved before it. When T2's volatile read sees true, the chain below holds, and T2 must see data = 42. (Demo 4: volatile ready fixes both bugs: the first spin goes to memory again, and data is written back before ready.)
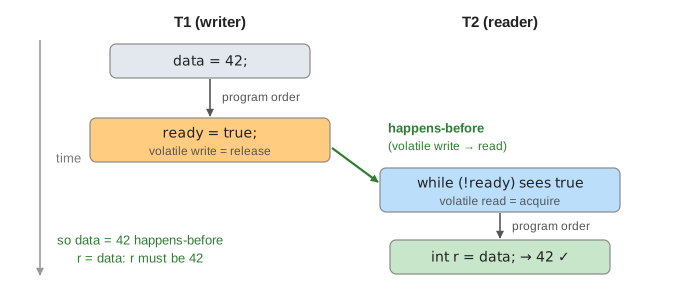
Only ready needs to be volatile: data is ordered by the chain. But volatile is about visibility and order, not atomicity: count++ on a volatile field is still a read, an add and a write, and two threads can lose updates. Use AtomicInteger (see Compare-and-Swap) or a lock for that.
The fix: synchronized
Put both sides in synchronized (lock). Unlocking a monitor is a release (T1's writes reach memory), and locking it is an acquire (T2 drops its old copies). An unlock happens-before every later lock of the same monitor. On top of that a monitor gives mutual exclusion: a thread that finds it held is BLOCKED. (Demo 5: synchronized, unlock then lock: T2 is blocked once, then reads ok = true and r = 42.) Both threads must lock the same object; a lock nobody else takes orders nothing.
| plain | volatile | synchronized | |
|---|---|---|---|
| other threads see the write | maybe, maybe never | yes | yes, after unlock → lock |
| earlier writes visible too | no | yes (release / acquire) | yes |
count++ safe | no | no | yes |
| a thread can block | no | no | yes |
What it costs in hardware
Volatile and locks are paid for with memory barriers. On x86 a volatile write is followed by a full barrier (a lock-prefixed instruction) that drains the store buffer; a volatile read is an ordinary load that the JIT may not move. On ARM the JIT uses load-acquire and store-release instructions. Cache coherence (MESI) keeps the caches themselves in agreement, so the stale copies here are registers and store buffers more than caches; see How a CPU Cache Finds, Misses and Replaces for the caches and HotSpot JIT Tiers for the compiler that hoists the read.
Safe publication
The same rules decide whether a new object is seen fully built. Publishing instance = new Helper() through a plain field can let another thread see the reference before the constructor's writes. That is why double-checked locking needs volatile Helper instance. Objects are published safely through a volatile field, a lock, a final field, a static initializer or a concurrent collection such as ConcurrentHashMap.
What the page leaves out
The real JMM is defined by actions, synchronization order and causality rules, not by store buffers and local copies; the picture here only shows effects the JMM allows. The page leaves out VarHandle access modes (opaque, acquire/release, plain), final field freezes, out-of-thin-air values, long/double tearing on 32-bit JVMs, thread start, join and interrupt edges, and the exact barriers each CPU needs. Spinning on a flag is shown only because it makes the bug easy to see: real code waits with wait/notify, a CountDownLatch or a future.